The brief
The client needed a way to interrogate their own files - contracts, operational PDFs, exports - without a specialist opening each one. The question was usually specific: a clause, a figure, a discrepancy across pages.
The assistant had to stay inside the uploaded material. A fluent answer that came from elsewhere would be worse than no answer.
How we approached it
Each file is opened, not summarised once and forgotten. PDF pages are read as text where that exists, and rendered for vision where it does not. CSV and text files are passed through as structured content. A prompt template selected for the job tells the model what kind of document it is looking at.
Token use is estimated before the call, so a 200-page dump does not silently fail halfway through.
What we built
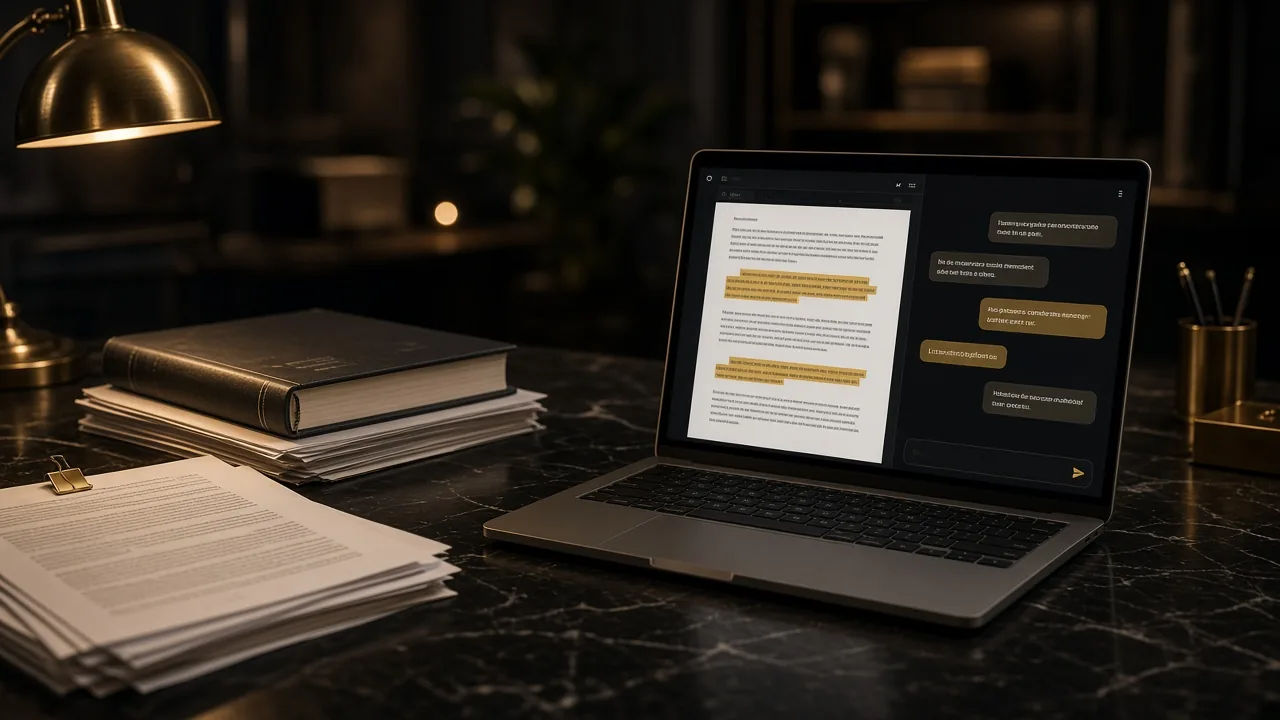
A web upload flow for one or more files, with a place to state the question or the extraction job. The backend extracts pages and tables, sends them with the chosen instruction, and returns the answer to the same screen.
This is the same family of work as a RAG system: the document is the source of truth, and the model is asked to stay on it.
This engagement is covered by a confidentiality agreement, so the client is not named and some implementation detail is described in general terms.